Every enterprise AI conversation I have now starts with the same question: "Where should this actually run?"
Cloud or on-prem? API or self-hosted? Neocloud? Most teams answer by default: the vendor relationship, pilot convenience, last year's decision. That worked for experiments. It won't hold for production, because recurring inference changes the placement economics.
The better question is: which workload belongs where?
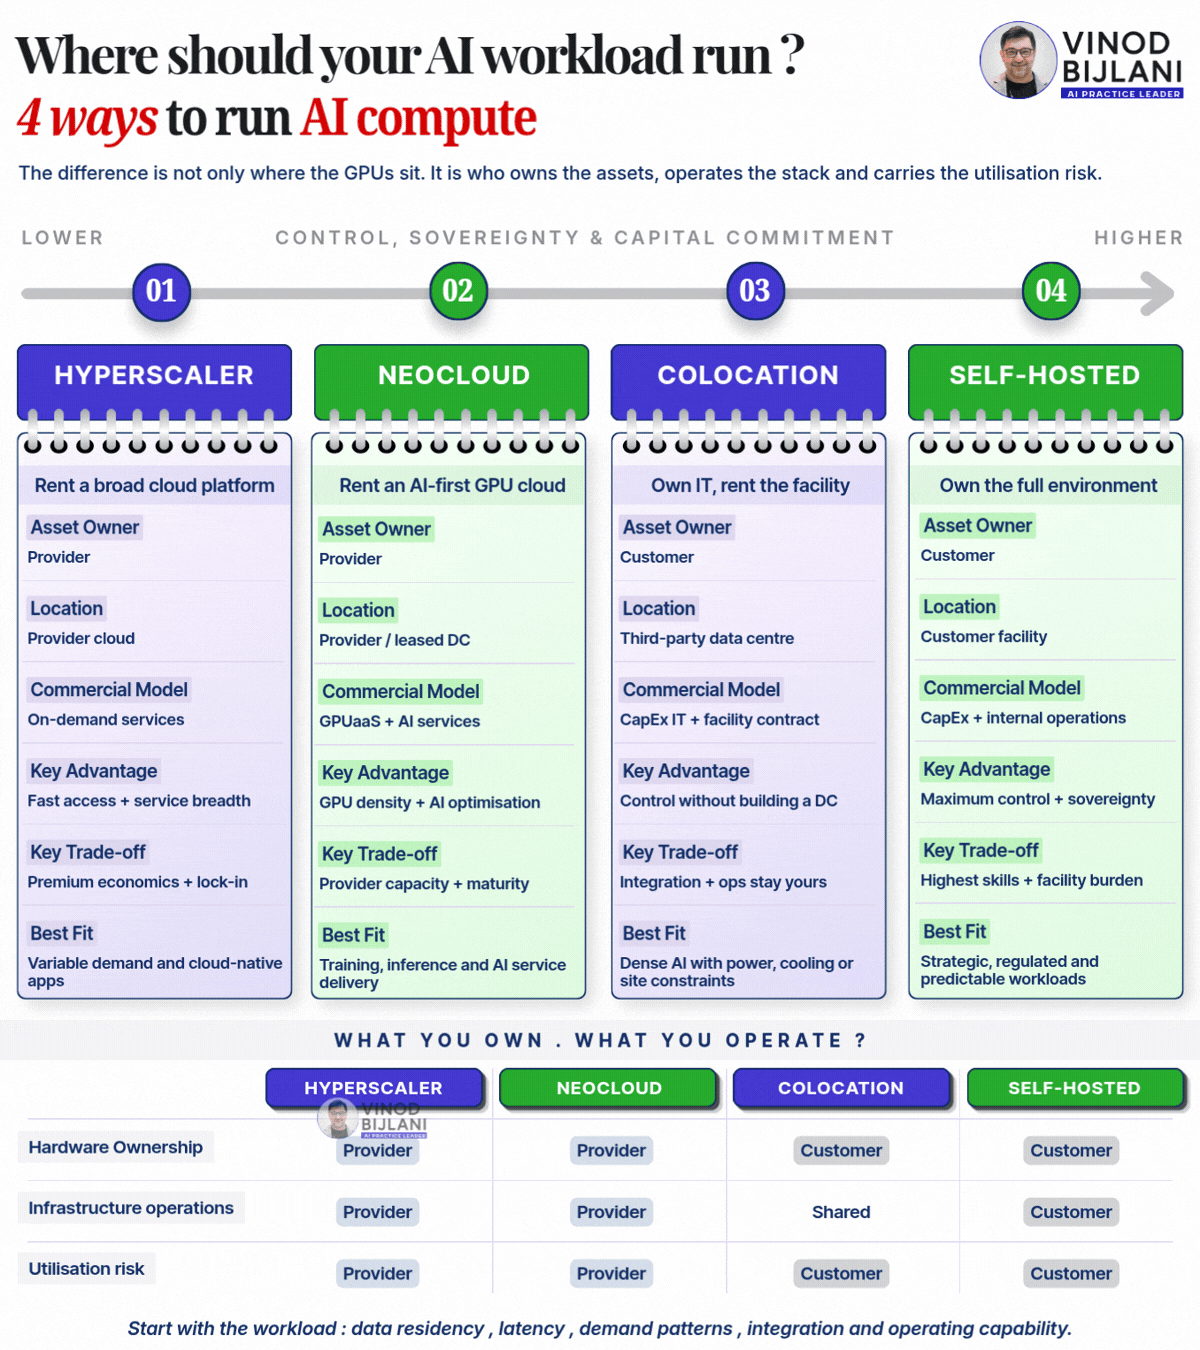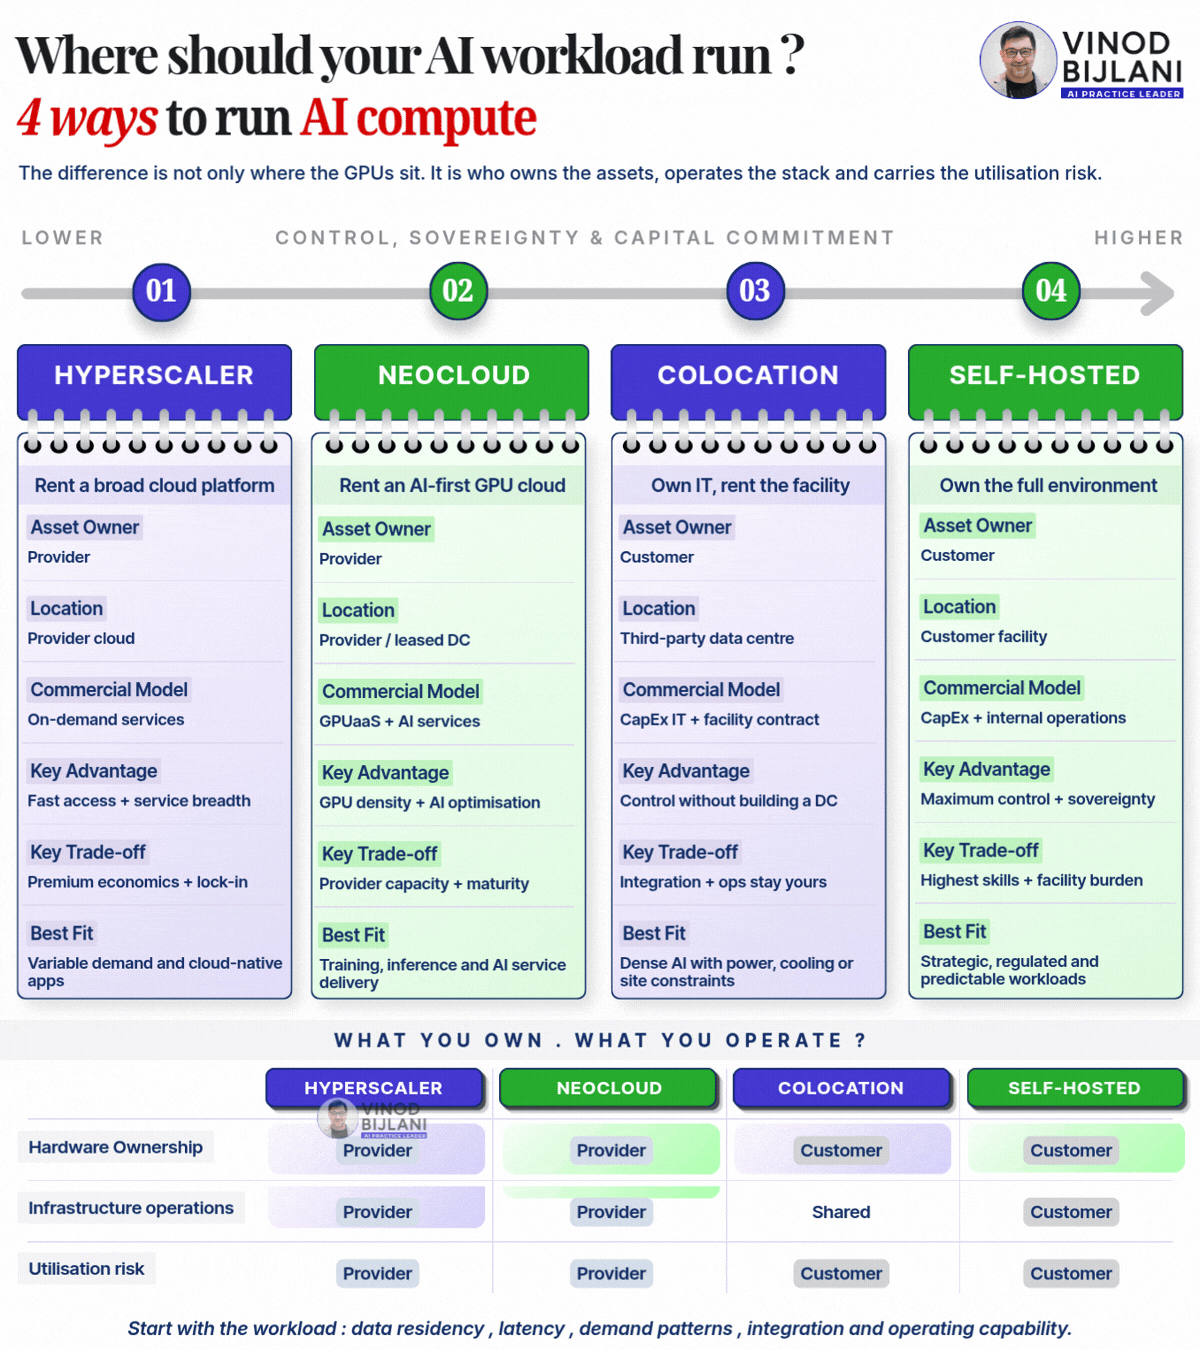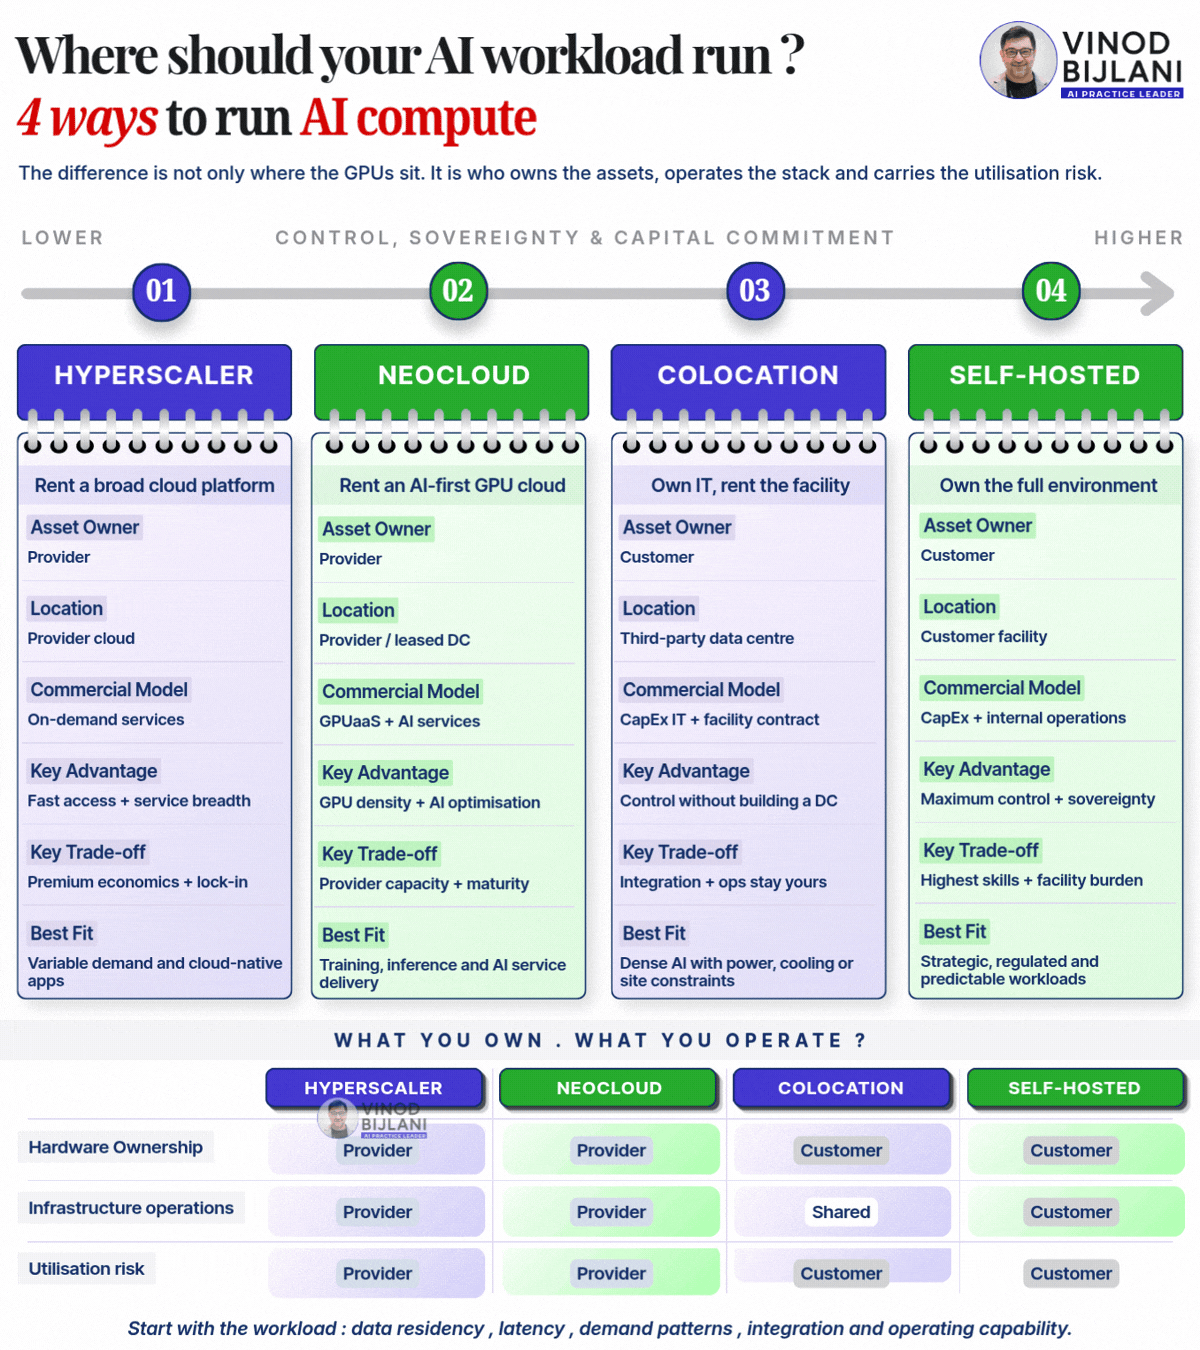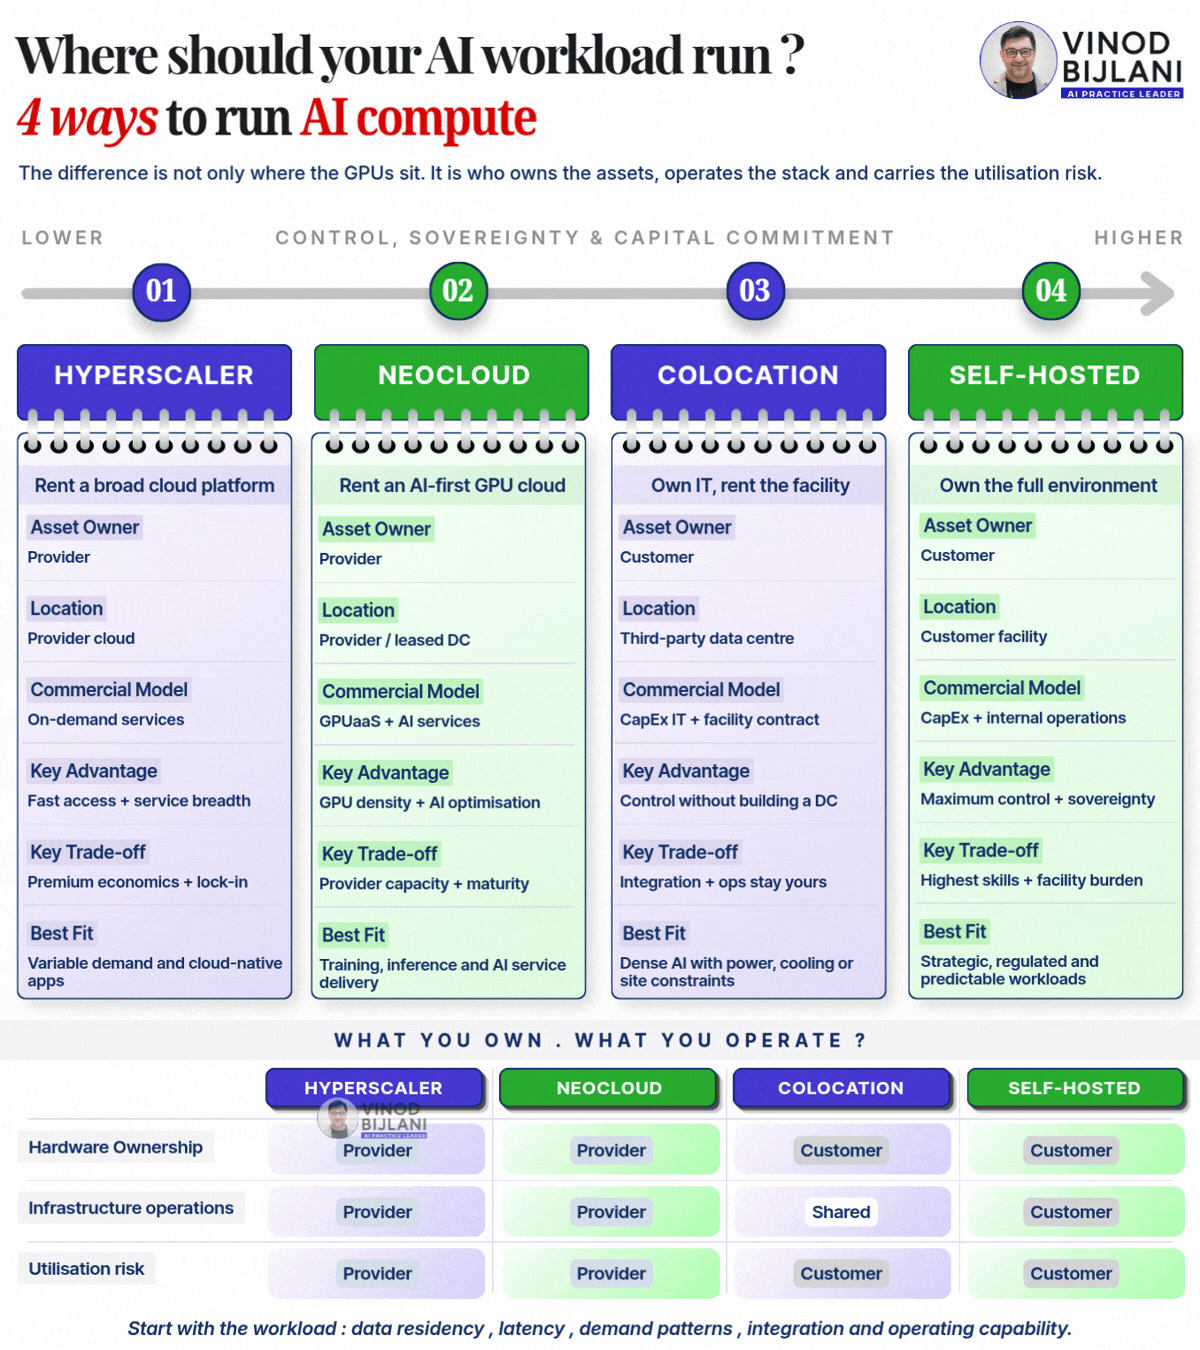
I believe the answer is hybrid AI, where cost, control and performance decide placement, not habit. In my latest Forbes Technology Council article I break hybrid AI into four placements: the hyperscaler as generalist, the neocloud as specialist, self-hosted as the sovereign option and the edge as the front line.
Three things leaders often miss
Your data travels further than you think. With retrieval-augmented generation, retrieved passages cross your boundary the moment they reach an external model, even if the database stays on-prem. Prompts, logs and outputs do too.
The cheapest model isn't always the cheapest outcome. Count retries, retrieval, data transfer and human correction, not just compute.
Fallbacks need rules. An outage should never silently route sensitive data to an unapproved service.
The common thread
Hybrid AI only works when every placement has a business reason. Decide it upfront. Govern it continuously. Revisit it when volumes, models or pricing change.
Where are most of your AI workloads running today: hyperscaler, neocloud, self-hosted, colocation, edge, or still deciding?